set.seed(1)
hist(rbeta(10000, 5, 5), ann = FALSE, col = 'blue')
In this chapter, we will learn to:
A histogram is a plot that can be used to examine the shape and spread of continuous data. It looks very similar to a bar graph and can be used to detect outliers and skewness in data. The histogram graphically shows the following:
To construct a histogram, the data is split into intervals called bins. The intervals may or may not be equal sized. For each bin, the number of data points that fall into it are counted (frequency). The Y axis of the histogram represents the frequency and the X axis represents the variable.
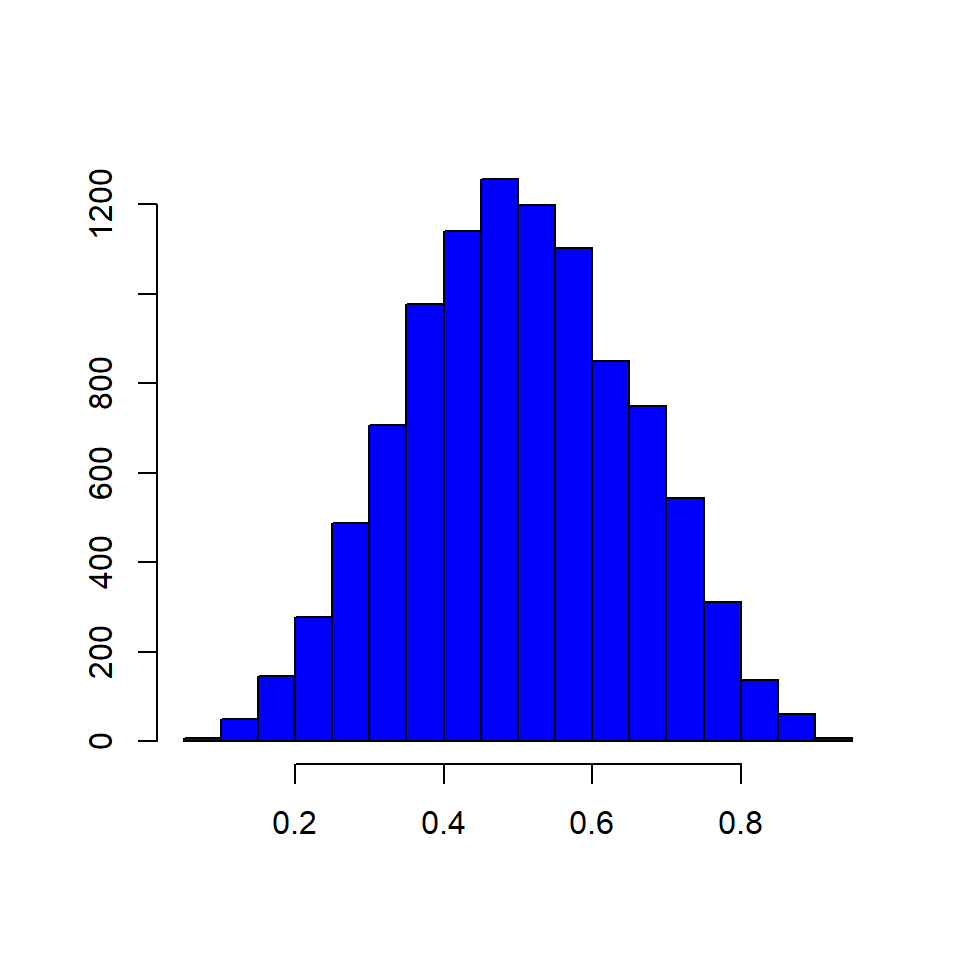
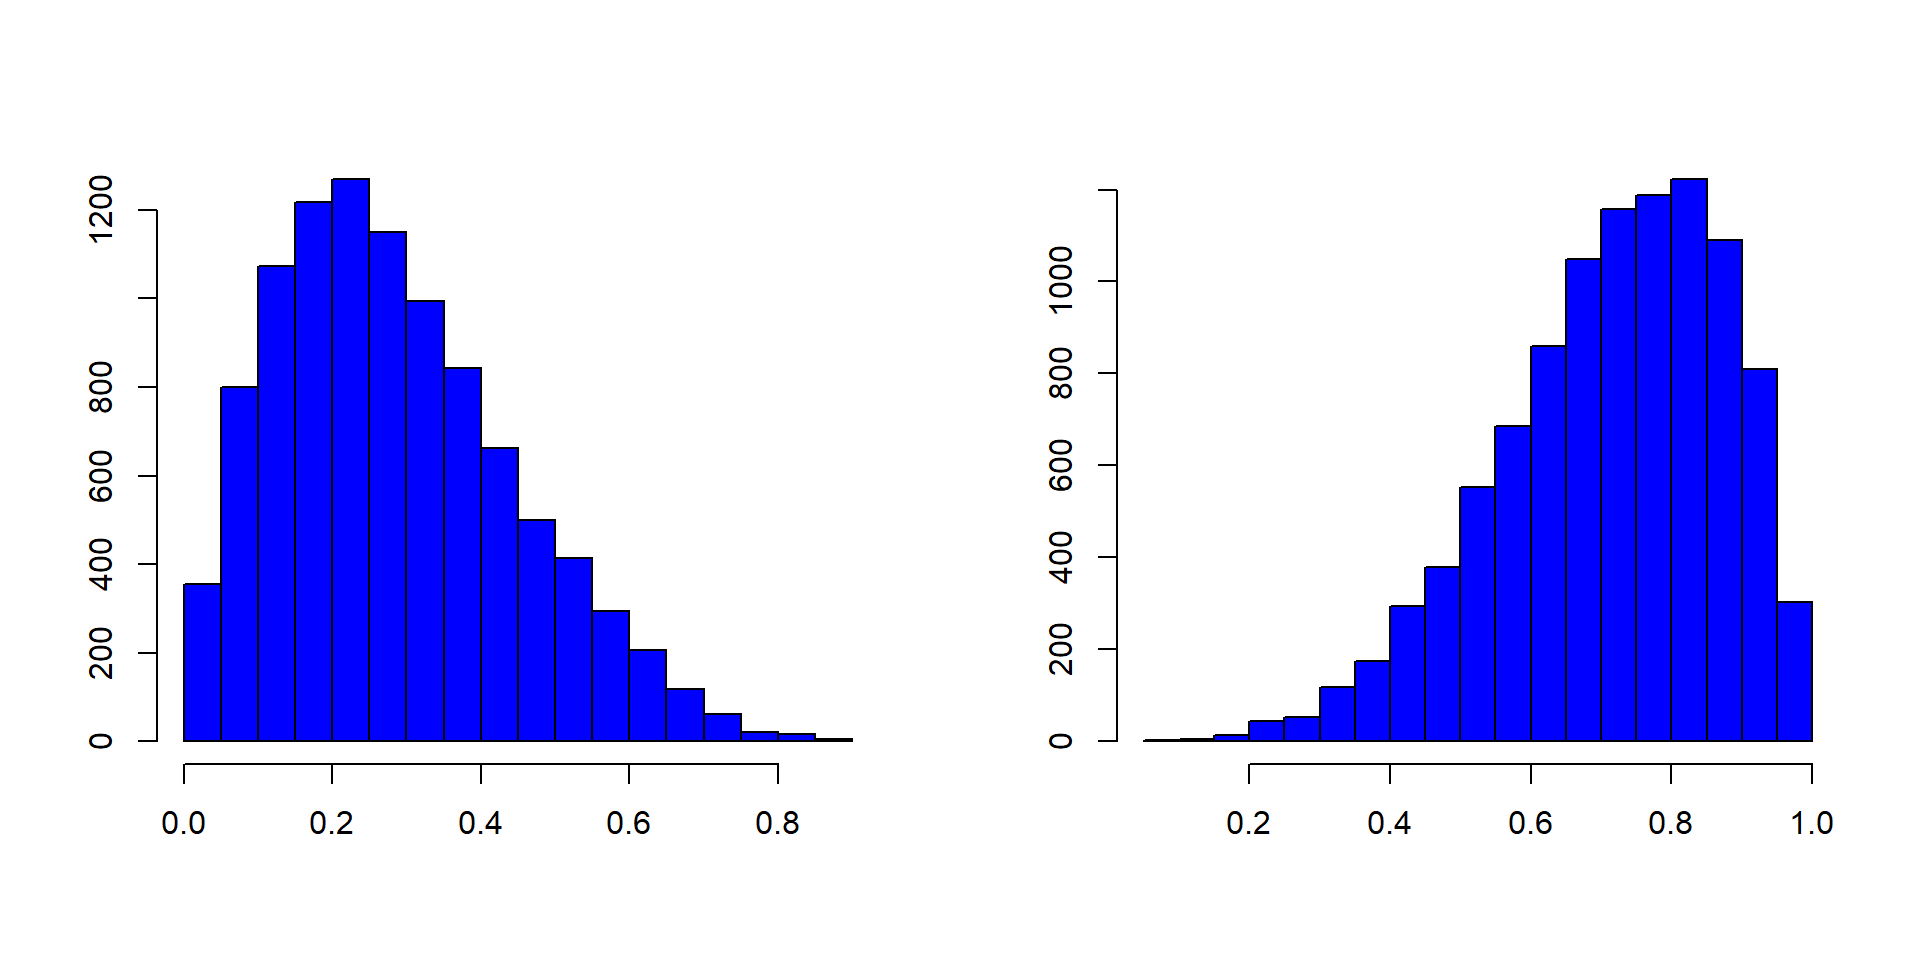
Before we learn how to create histograms, let us see how normal and skewed distributions look when represented by a histogram.
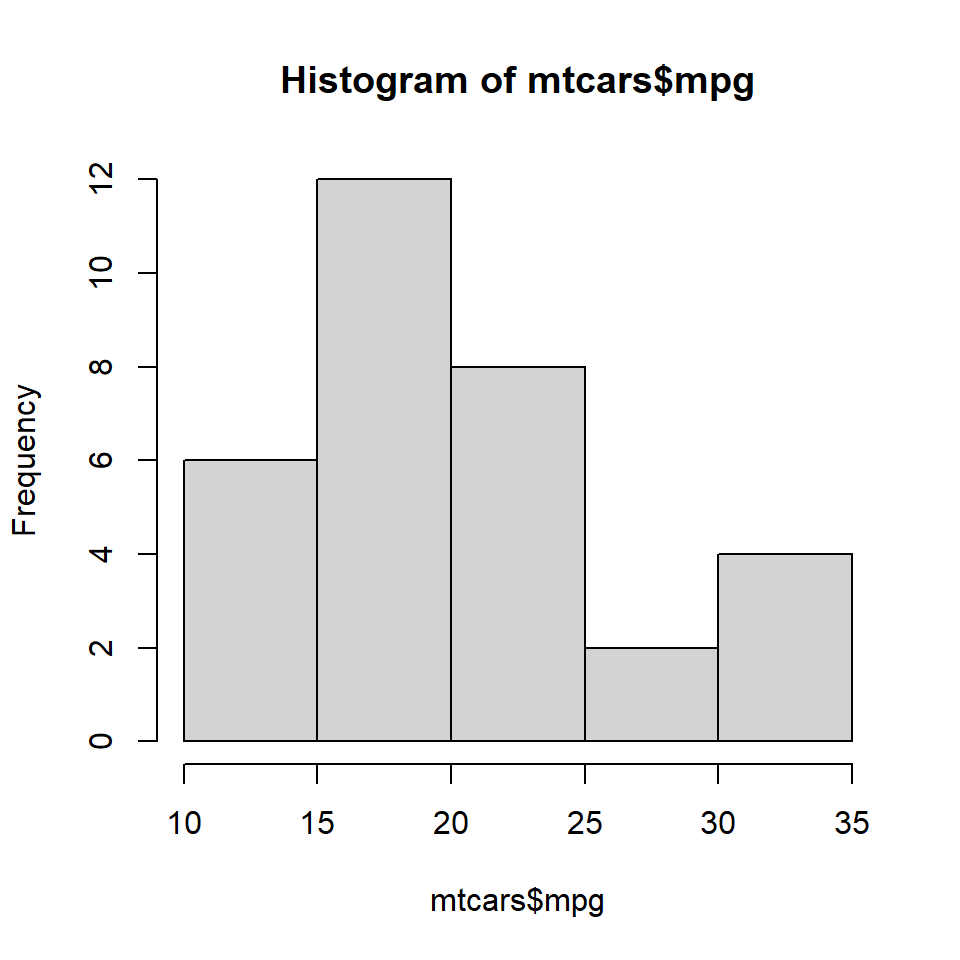
Histograms are created using the hist() function in R. The minimum input required to create a bare bones histogram is a continuous variable. Below is an example:
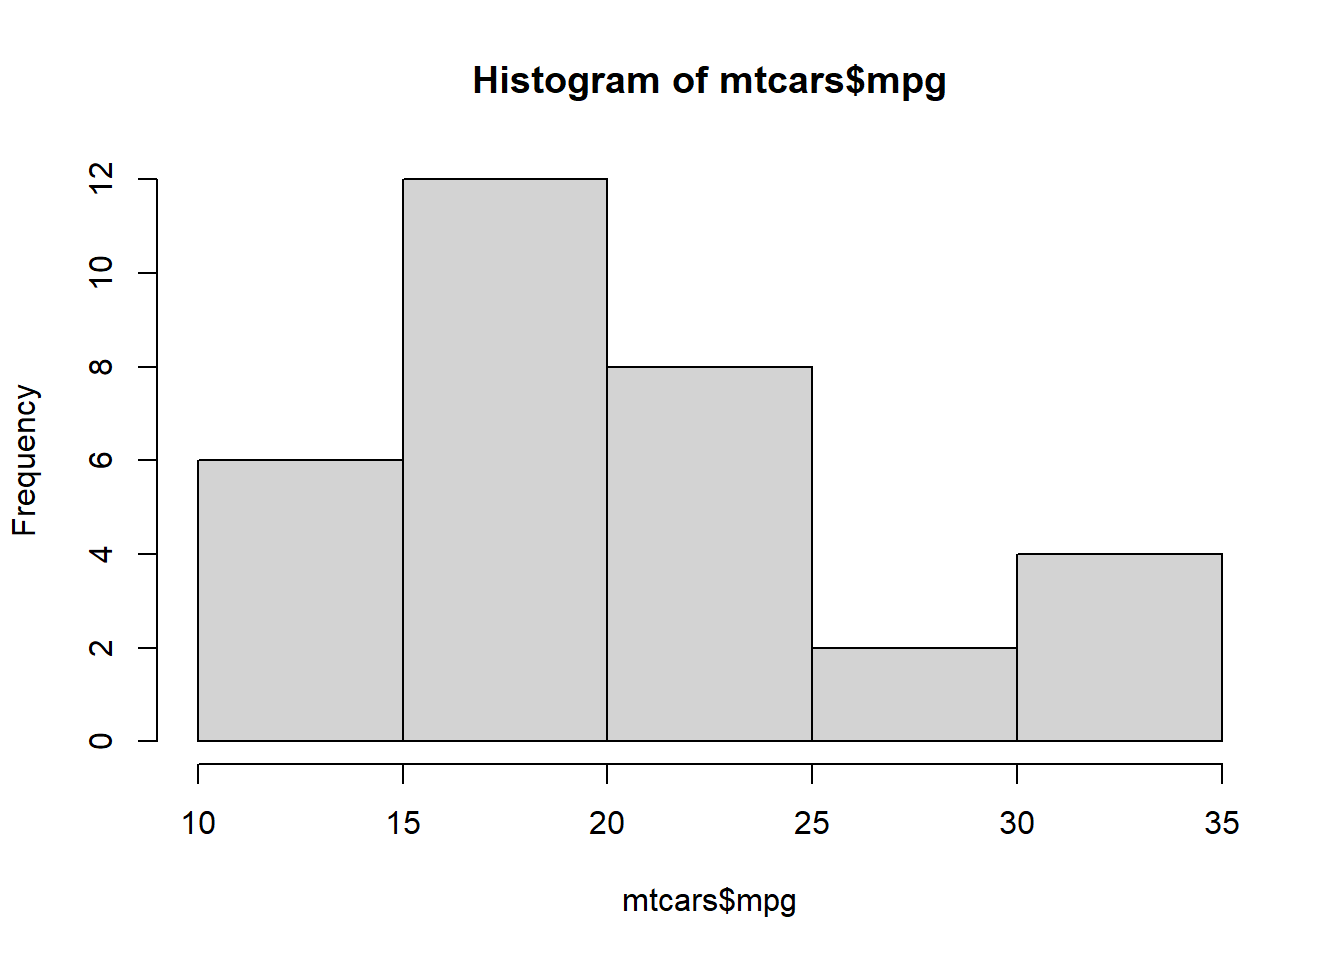
The hist() functions returns details of the histogram which can be accessed by assigning the histogram to a variable. Let us assign the above histogram to a variable h and use the $ symbol to access the details stored in the variable.

# display number of breaks
h$breaks
## [1] 10 15 20 25 30 35
# frequency of the intervals
h$counts
## [1] 6 12 8 2 4
# frequency density
h$density
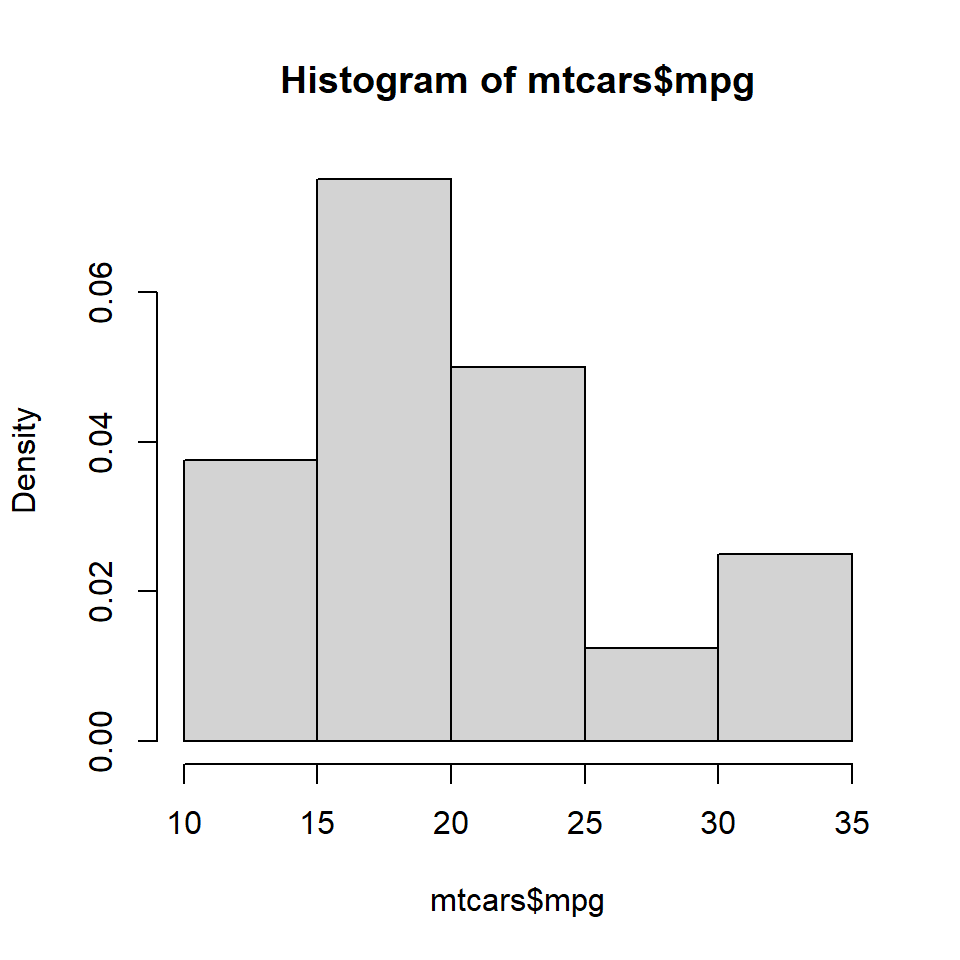
## [1] 0.0375 0.0750 0.0500 0.0125 0.0250
# mid points of the intervals
h$mids
## [1] 12.5 17.5 22.5 27.5 32.5
# varible name
h$xname
## [1] "mtcars$mpg"
# whether intervals are of equal size
h$equidist
## [1] TRUEThe hist() function creates equidistant intervals by default. We can specify the number of bins using the breaks argument.
The below plot displays histograms with different number of bins:
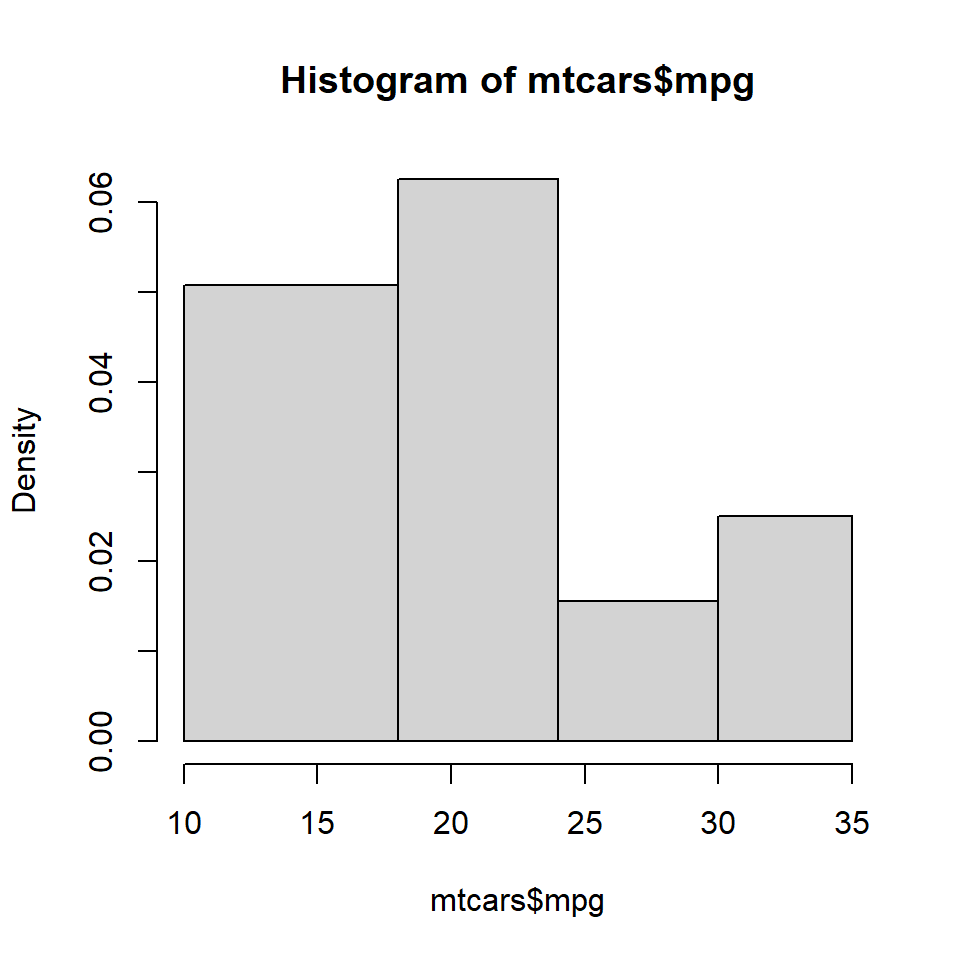
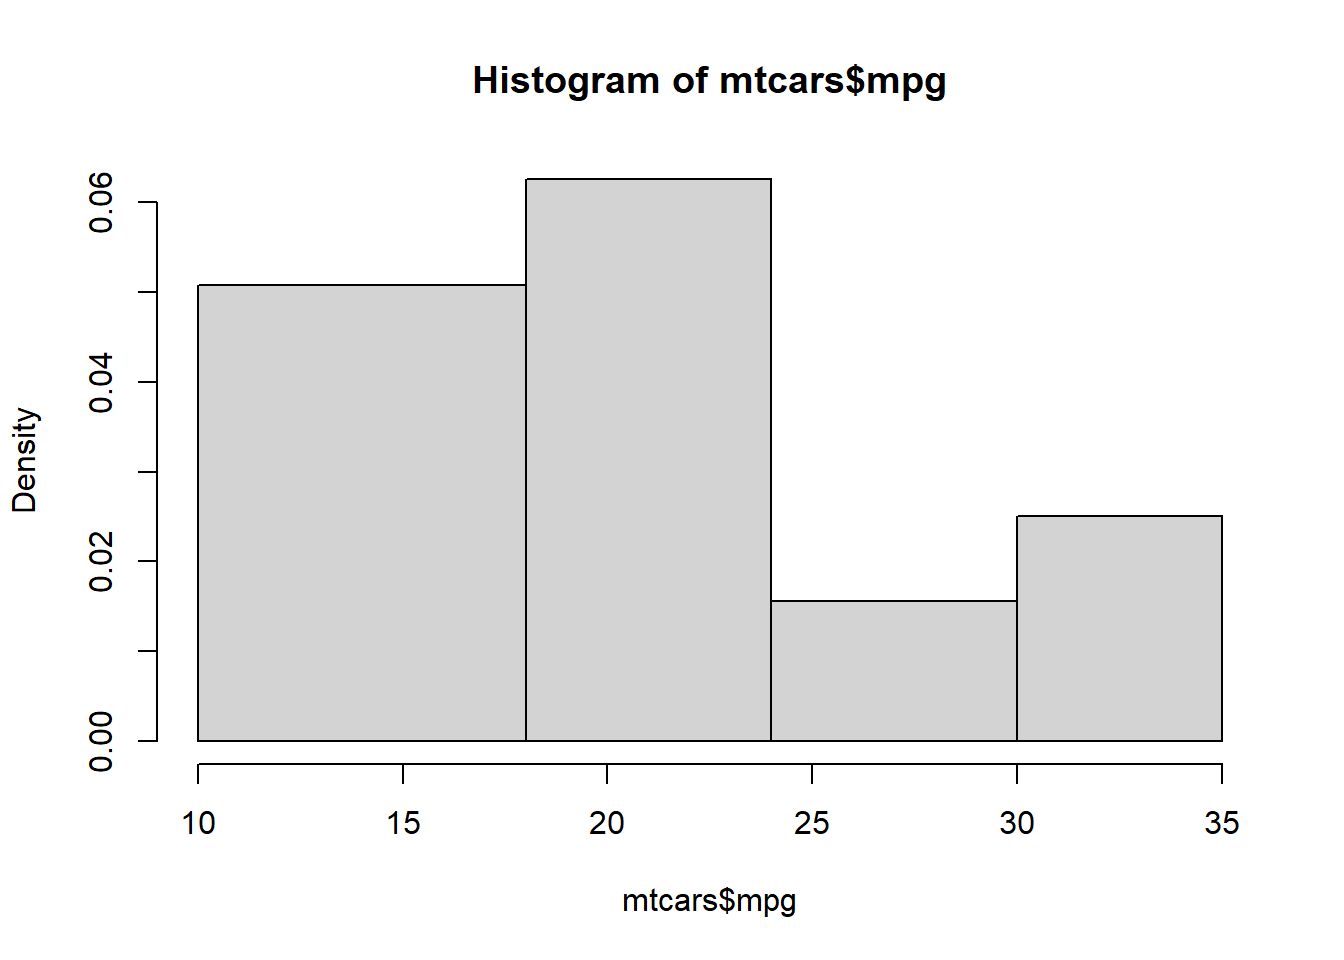
If we want to create histograms with specific intervals, the breaks argument can be supplied with the intervals.
If you observe the Y axis, it does not represent frequency any more. Instead, it represents the frequency density. What is frequency density?
Frequency Density = Relative Frequency / Class Width
Relative Frequency = Frequency / Total Observations

frequency <- h$counts
class_width <- c(8, 6, 6, 5)
rel_freq <- frequency / length(mtcars$mpg)
freq_density <- rel_freq / class_width
d <- data.frame(frequency = frequency, class_width = class_width, relative_frequency = rel_freq, frequency_density = freq_density)
d frequency class_width relative_frequency frequency_density
1 13 8 0.40625 0.05078125
2 12 6 0.37500 0.06250000
3 3 6 0.09375 0.01562500
4 4 5 0.12500 0.02500000
When multiplied by the class width, the product will always sum upto 1.
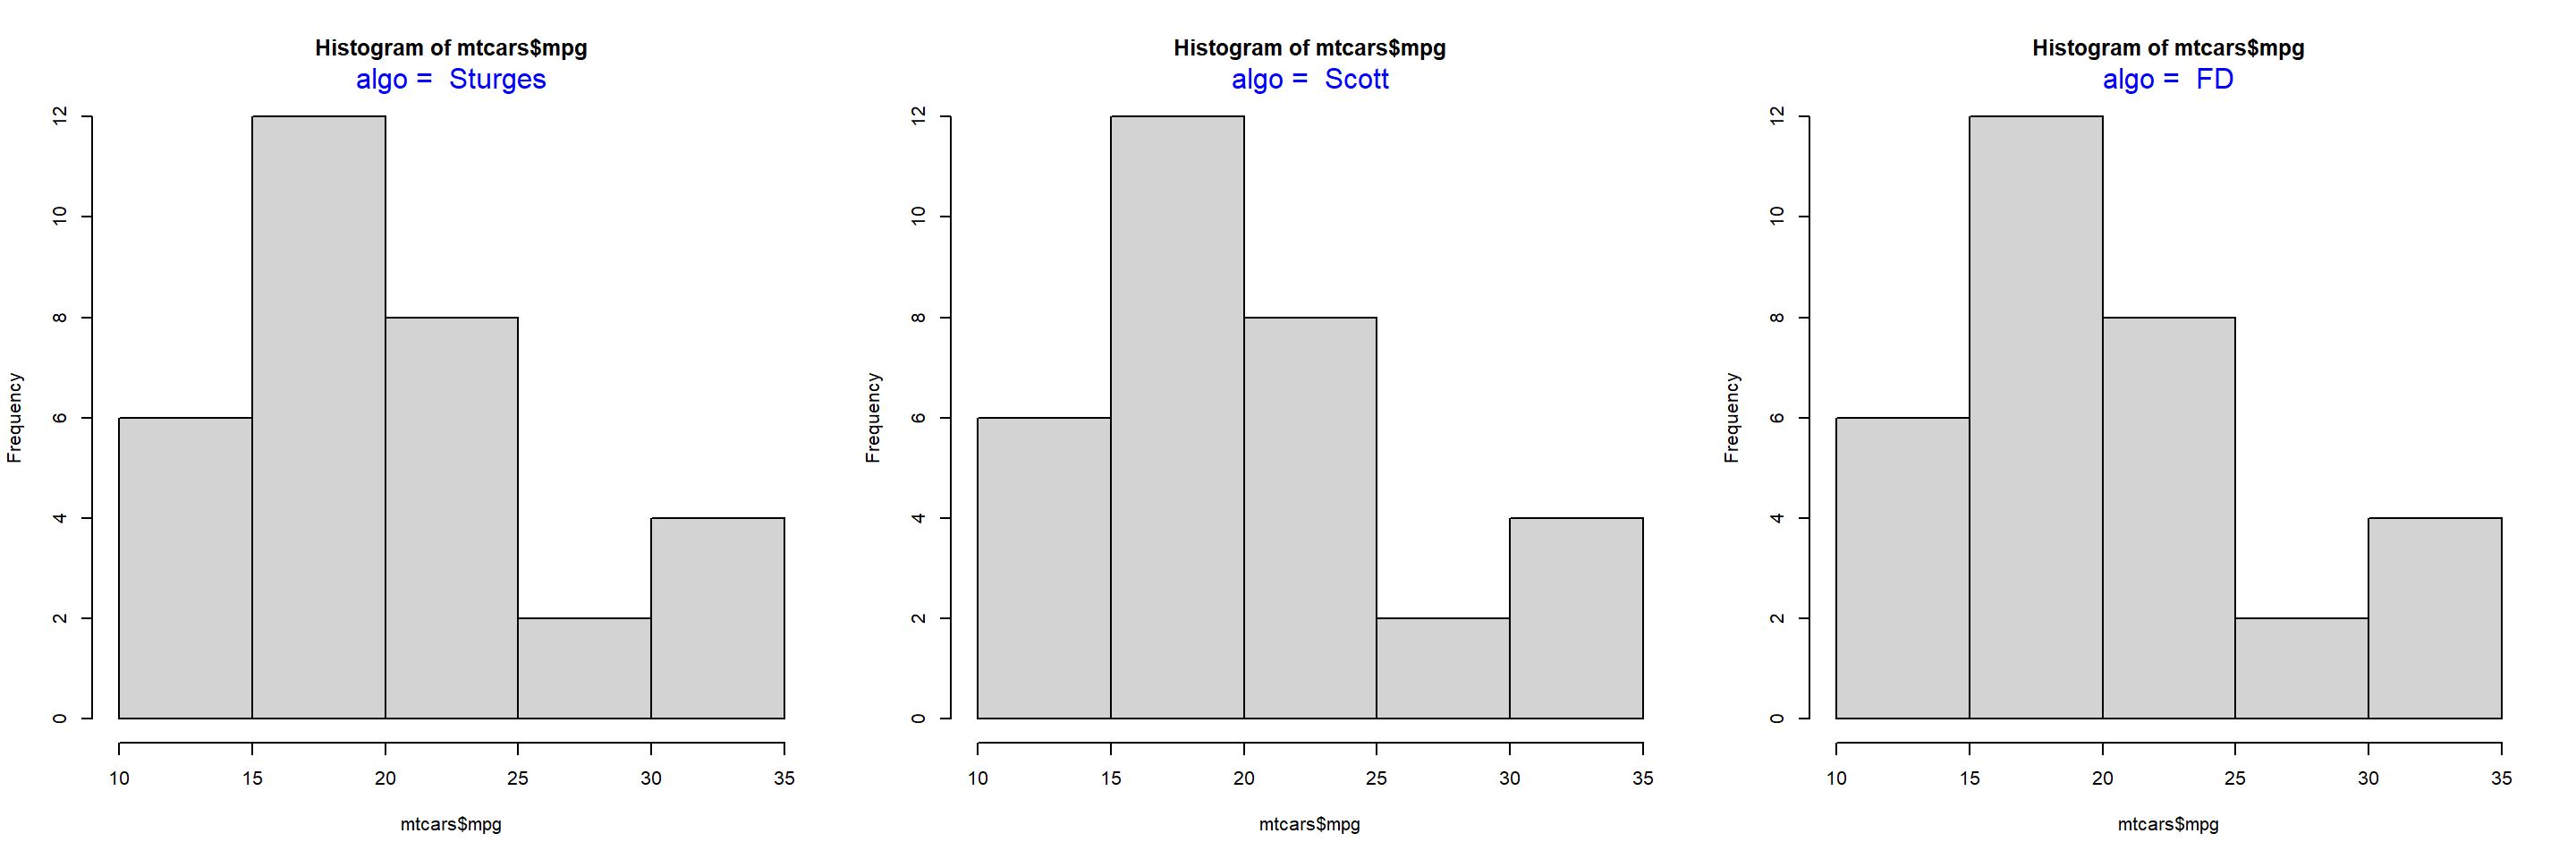
We will learn more about frequency density in a bit. Before we end this section, we need to learn about one more way to specify the intervals of the histogram, algorithms. The hist() function allows us to specify the following algorithms:
In the below plot, we examine how th algorithms work:
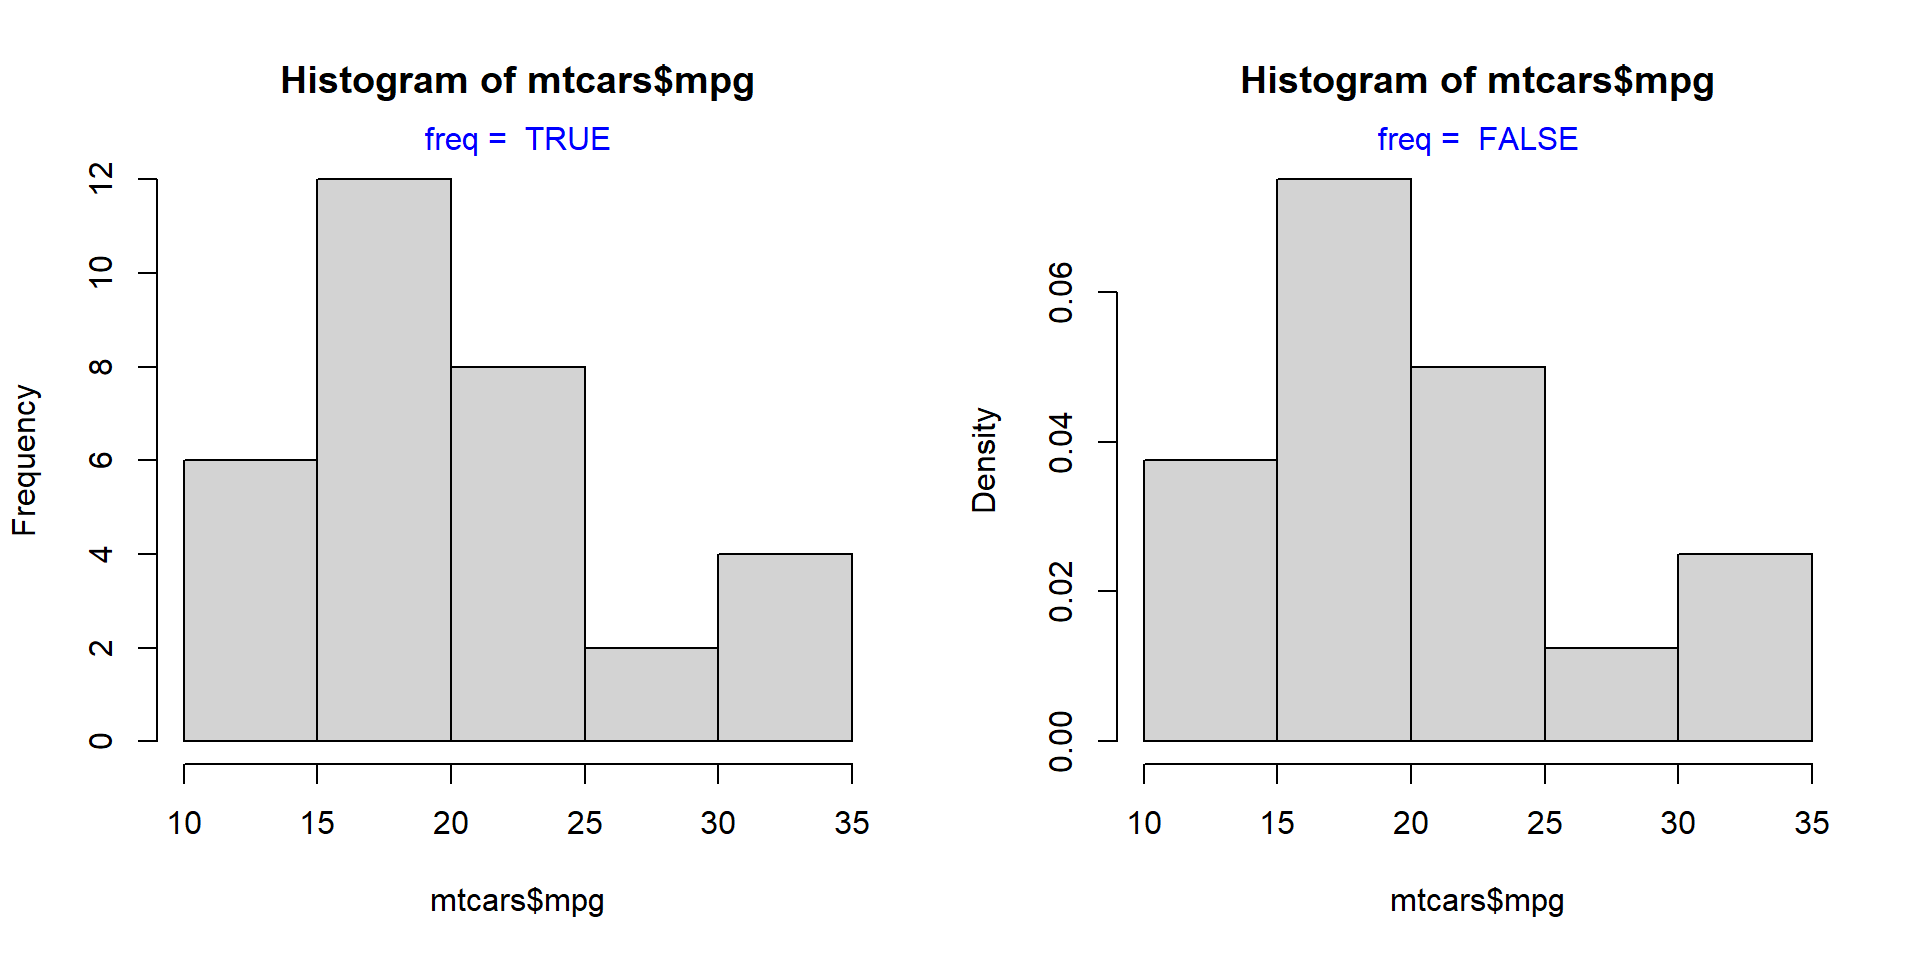
Let us come back to frequency density. If you want the Y axis of the histogram to represent frequency density instead of counts, set the freq argument to FALSE.
init <- par(no.readonly = TRUE)
par(mfrow = c(1, 2))
values <- c(TRUE, FALSE)
for (i in values) {
hist(mtcars$mpg, freq = i)
mtext(paste("freq = ", i), side = 3, col = "blue")
}
The same result can be achieved by using the probability argument as well. It takes only logical values as inputs and the default is FALSE. If set to TRUE, the Y axis will represent the frequency density instead of counts.
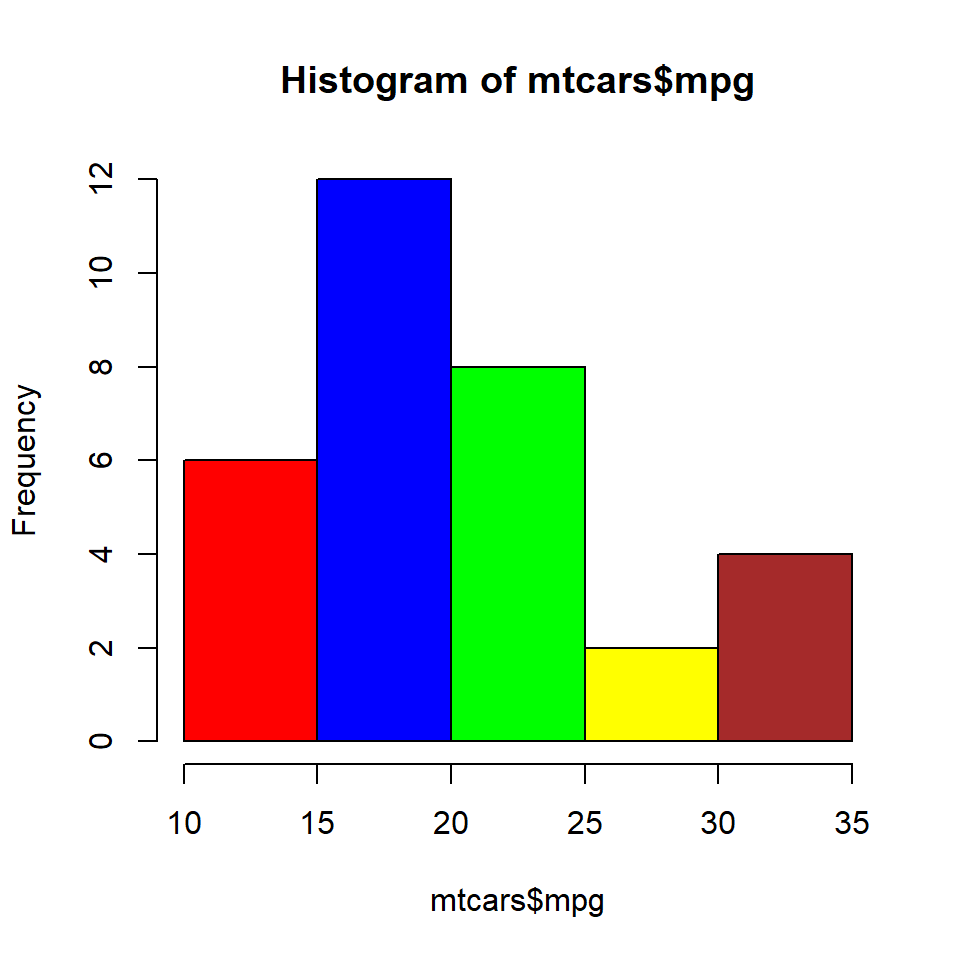
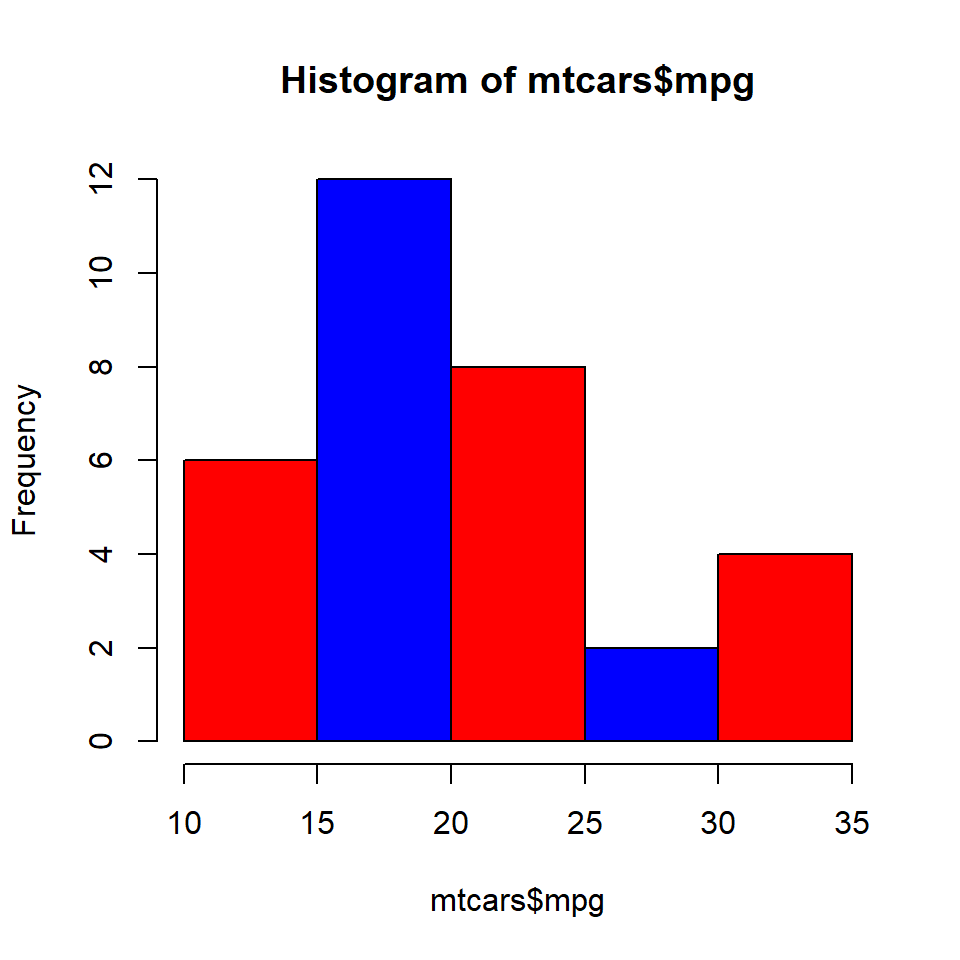
To add colors to the bars of the histogram, use the col argument. If the number of colors specified is less than the number of bars, the colors are recycled. Below are a few examples:
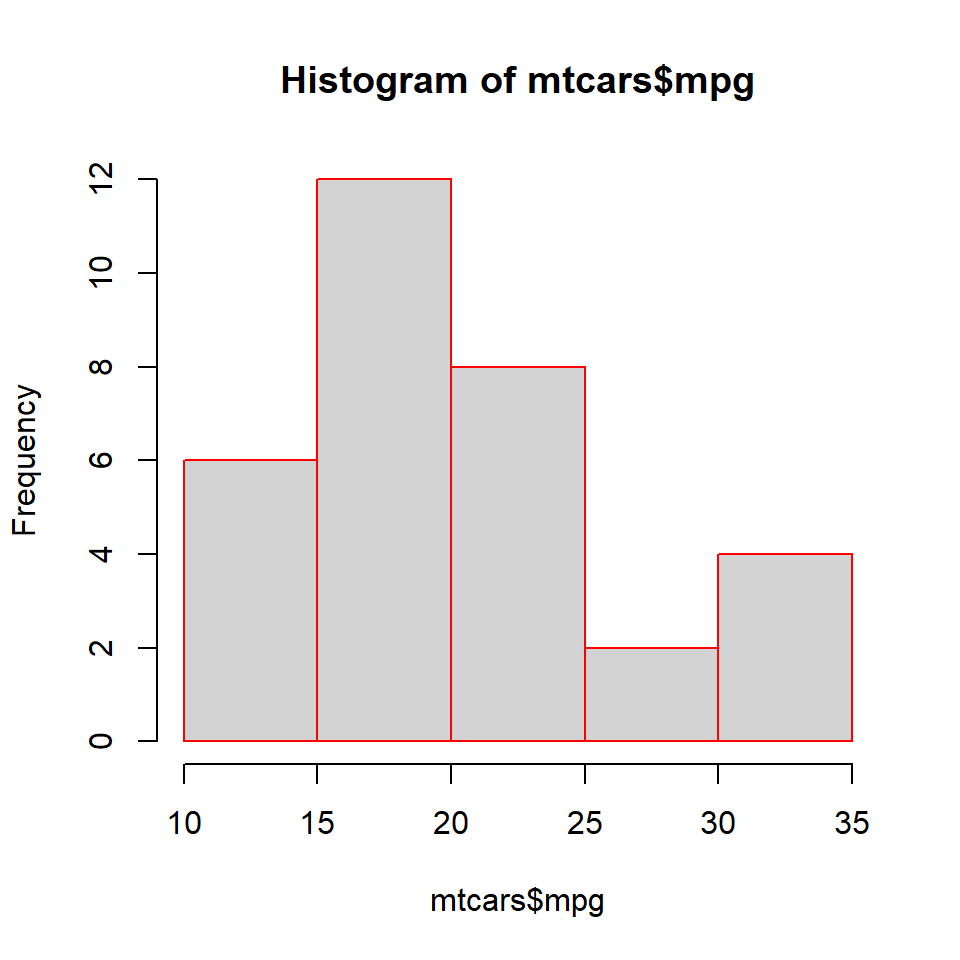
Colors can be specified for the borders of the histogrambars using the border argument.
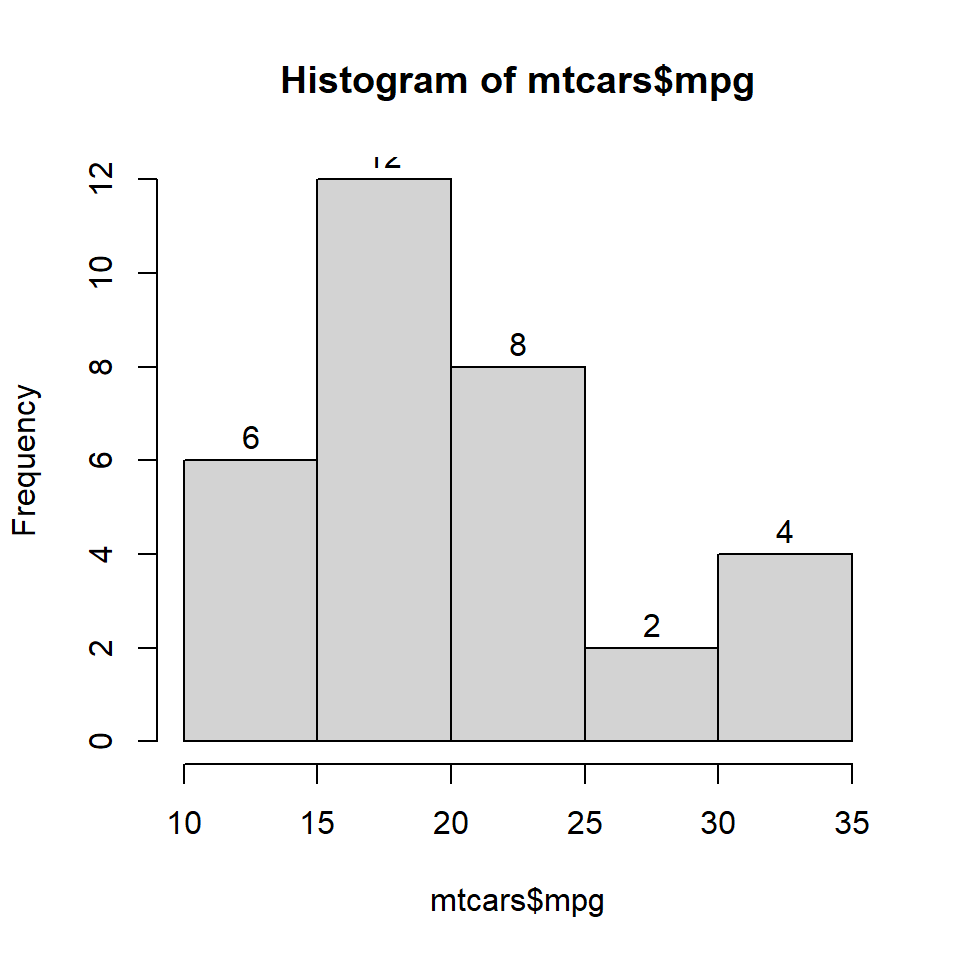
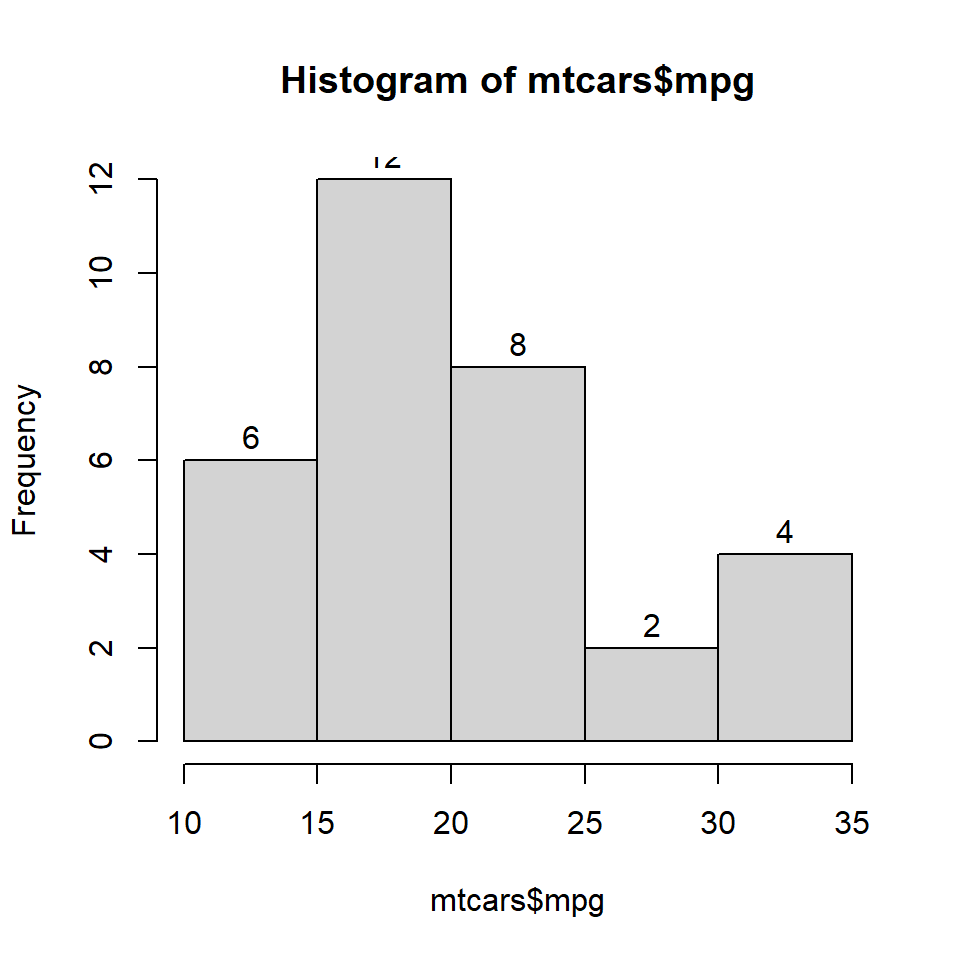
In certain cases, we might want to add the frequency counts on the histogram bars. It is easier for the user to know the frequencies of each bin when they are present on top of the bars. Let us add the frequency counts on top of the bars using the labels argument. We can either set it to TRUE or a character vector containing the label values. Let us look at both the methods.
Set labels to TRUE.
Specify the label values in a character vector.
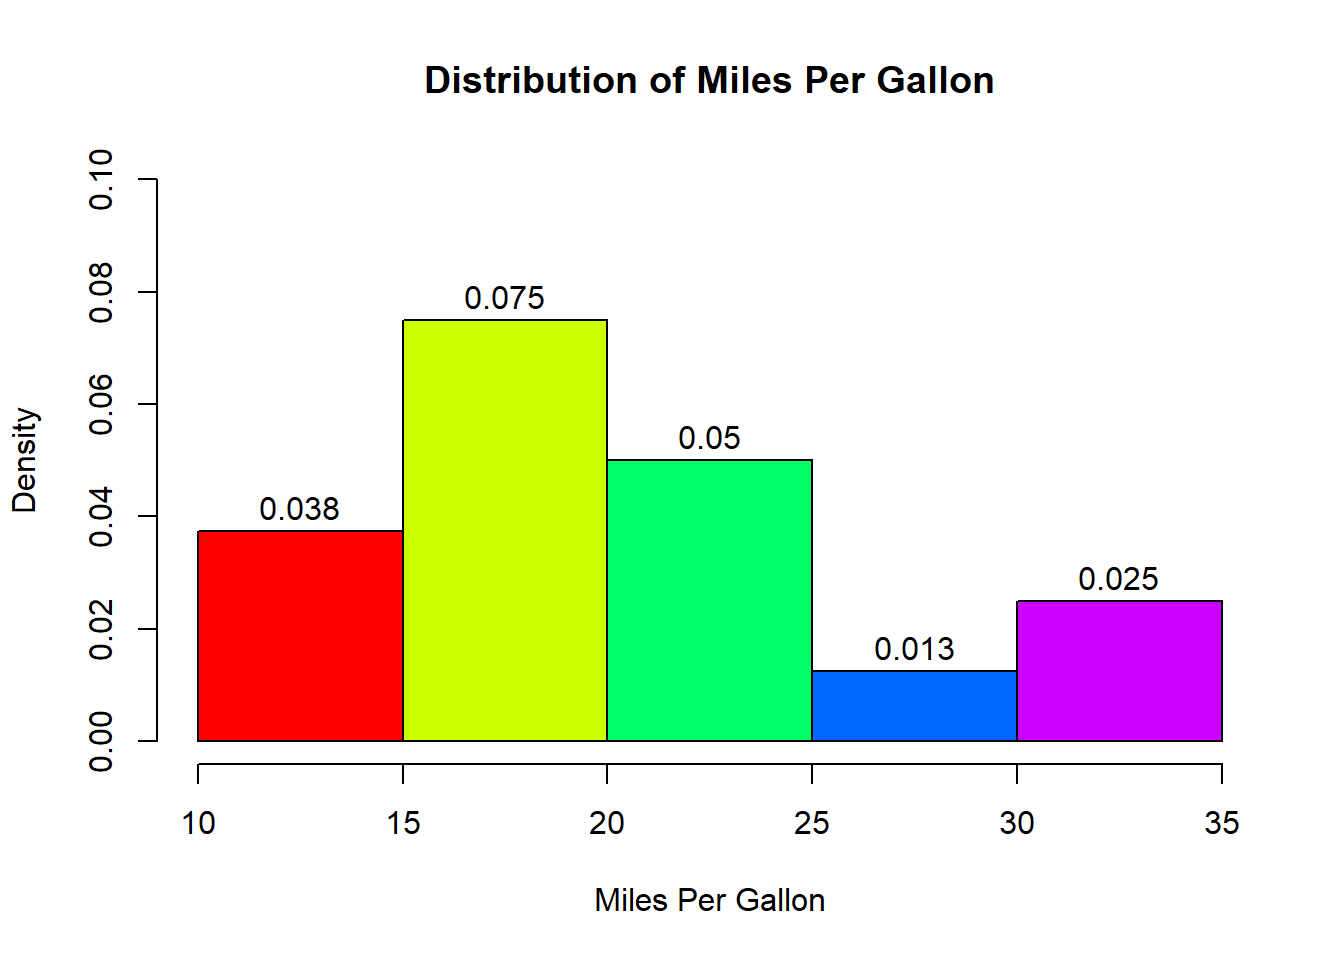
Let us add a title and axis labels to the histogram.
---
description: "Base R histograms with hist(): choosing breaks and the interval count, frequency tables, colour and borders, frequency labels, and skewed data with rbeta()."
---
# Histograms {#hist}
## Introduction
In this chapter, we will learn to:
- create a bare bones histogram
- specify the number of bins/intervals
- represent frequency density on the Y axis
- add colors to the bars and the border
- add labels to the bars
A histogram is a plot that can be used to examine the shape and spread of continuous data. It looks very similar to a bar graph and can be used to detect outliers and skewness in data. The histogram graphically shows the following:
- center (location) of the data
- spread (dispersion) of the data
- skewness
- outliers
- presence of multiple modes
To construct a histogram, the data is split into intervals called bins. The intervals may or may not be equal sized. For each bin, the number of data points that fall into it are counted (frequency). The Y axis of the histogram represents the frequency and the X axis represents the variable.
## Distributions
Before we learn how to create histograms, let us see how normal and skewed distributions look when represented by a histogram.
### Normal Distribution
```{r hist1, fig.align='center', fig.height=5, fig.width=5}
set.seed(1)
hist(rbeta(10000, 5, 5), ann = FALSE, col = 'blue')
```
### Skewed Distributions
```{r hist2, fig.align='center', fig.width=10, fig.height=5}
set.seed(1)
init <- par(no.readonly = TRUE)
par(mfrow = c(1, 2))
hist(rbeta(10000, 2, 5), ann = FALSE, col = 'blue')
hist(rbeta(10000, 5, 2), ann = FALSE, col = 'blue')
par(init)
```
## Basics
Histograms are created using the `hist()` function in R. The minimum input required to create a bare bones histogram is a continuous variable. Below is an example:
```{r hist3, fig.align='center', fig.height=5, fig.width=5}
hist(mtcars$mpg)
```
The `hist()` functions returns details of the histogram which can be accessed by assigning the histogram to a variable. Let us assign the above histogram to a variable `h` and use the `$` symbol to access the details stored in the variable.
```{r hist4, collapse=TRUE}
# store the results of hist function
h <- hist(mtcars$mpg)
# display number of breaks
h$breaks
# frequency of the intervals
h$counts
# frequency density
h$density
# mid points of the intervals
h$mids
# varible name
h$xname
# whether intervals are of equal size
h$equidist
```
## Bins
The `hist()` function creates equidistant intervals by default. We can specify the number of bins using the `breaks` argument.
```{r, fig.align='center', fig.height=5, fig.width=5}
#| label: fig-hist-breaks
#| fig-cap: "The same data with an explicit number of breaks"
#| fig-alt: "A histogram of a skewed variable. Specifying breaks changes the interval width and therefore the bar heights and count, without changing the data. The narrower intervals produce taller, thinner bars."
hist(mtcars$mpg, breaks = 10)
```
The below plot displays histograms with different number of bins:
```{r, fig.align='center', fig.width=10, fig.height=10}
#| label: fig-hist-break-gallery
#| fig-cap: "A gallery of histograms of the same data at different interval widths"
#| fig-alt: "A grid of histograms of the same right-skewed data. Each panel uses a different setting for the interval breaks, from very few wide bars through to many narrow ones, showing how bar height and apparent shape change purely because of the interval choice."
init <- par(no.readonly = TRUE)
par(mfrow = c(2, 2))
values <- c(5, 10, 15, 20)
for (i in values) {
hist(mtcars$mpg, breaks = i)
mtext(paste("breaks = ", i), side = 3, col = "blue")
}
par(init)
```
## Intervals
If we want to create histograms with specific intervals, the `breaks` argument can be supplied with the intervals.
```{r hist7, fig.align='center', fig.height=5, fig.width=5}
hist(mtcars$mpg, breaks = c(10, 18, 24, 30, 35))
```
If you observe the Y axis, it does not represent frequency any more. Instead, it represents the frequency density. What is frequency density?
### Frequency Density
Frequency Density = Relative Frequency / Class Width
Relative Frequency = Frequency / Total Observations
```{r hist8}
h <- hist(mtcars$mpg, breaks = c(10, 18, 24, 30, 35))
frequency <- h$counts
class_width <- c(8, 6, 6, 5)
rel_freq <- frequency / length(mtcars$mpg)
freq_density <- rel_freq / class_width
d <- data.frame(frequency = frequency, class_width = class_width, relative_frequency = rel_freq, frequency_density = freq_density)
d
```
When multiplied by the class width, the product will always sum upto 1.
```{r hist9}
sum(d$frequency_density * d$class_width)
```
We will learn more about frequency density in a bit. Before we end this section, we need to learn about one more way to specify the intervals of the histogram, algorithms. The `hist()` function allows us to specify the following algorithms:
- Sturges (default)
- Scott
- Freedman-Diaconis (FD)
In the below plot, we examine how th algorithms work:
```{r hist10, fig.align='center', fig.width=15, fig.height=5}
init <- par(no.readonly = TRUE)
par(mfrow = c(1, 3))
values <- c("Sturges", "Scott", "FD")
for (i in values) {
hist(mtcars$mpg, breaks = i)
mtext(paste("algo = ", i), side = 3, col = "blue")
}
par(init)
```
## Frequency Distribution II
Let us come back to frequency density. If you want the Y axis of the histogram to represent frequency density instead of counts, set the `freq` argument to `FALSE`.
```{r hist11, fig.align='center', fig.width=10, fig.height=5}
init <- par(no.readonly = TRUE)
par(mfrow = c(1, 2))
values <- c(TRUE, FALSE)
for (i in values) {
hist(mtcars$mpg, freq = i)
mtext(paste("freq = ", i), side = 3, col = "blue")
}
par(init)
```
The same result can be achieved by using the `probability` argument as well. It takes only logical values as inputs and the default is `FALSE`. If set to `TRUE`, the Y axis will represent the frequency density instead of counts.
```{r hist12, fig.align='center', fig.height=5, fig.width=5}
hist(mtcars$mpg, probability = TRUE)
```
## Color
To add colors to the bars of the histogram, use the `col` argument. If the number of colors specified is less than the number of bars, the colors are recycled. Below are a few examples:
### Single Color
```{r, fig.align='center', fig.height=5, fig.width=5}
#| label: fig-hist-freq
#| fig-cap: "Frequency labels drawn on top of the histogram bars"
#| fig-alt: "A histogram of a symmetric variable with the count for each interval printed above its bar, so each bar is labelled with the number of observations it contains."
hist(mtcars$mpg, col = 'blue')
```
### Different Colors
```{r hist14, fig.align='center', fig.height=5, fig.width=5}
hist(mtcars$mpg, col = c('red', 'blue', 'green', 'yellow', 'brown'))
```
### Recycled Colors
```{r hist15, fig.align='center', fig.height=5, fig.width=5}
hist(mtcars$mpg, col = c('red', 'blue'))
```
## Border Color
Colors can be specified for the borders of the histogrambars using the `border` argument.
```{r hist20, fig.align='center', fig.height=5, fig.width=5}
hist(mtcars$mpg, border = 'red')
```
### Different Colors
```{r, fig.align='center', fig.height=5, fig.width=5}
#| label: fig-hist-beta
#| fig-cap: "A right-skewed sample drawn with rbeta()"
#| fig-alt: "A histogram of a strongly right-skewed sample. Most observations pile up in the first few intervals near zero and a long thin tail stretches to the right, so the mean sits well above the median."
hist(mtcars$mpg, border = c('red', 'blue', 'green', 'yellow', 'brown'))
```
## Labels
In certain cases, we might want to add the frequency counts on the histogram bars. It is easier for the user to know the frequencies of each bin when they are present on top of the bars. Let us add the frequency counts on top of the bars using the `labels` argument. We can either set it to `TRUE` or a character vector containing the label values. Let us look at both the methods.
### Method 1
Set `labels` to `TRUE`.
```{r hist17, fig.align='center', fig.height=5, fig.width=5}
hist(mtcars$mpg, labels = TRUE)
```
### Method 2
Specify the label values in a character vector.
```{r hist18, fig.align='center', fig.height=5, fig.width=5}
hist(mtcars$mpg, labels = c("6", "12", "8", "2", "4"))
```
## Putting it all together
Let us add a title and axis labels to the histogram.
```{r hist19}
hist(mtcars$mpg, labels = TRUE, prob = TRUE,
ylim = c(0, 0.1), xlab = 'Miles Per Gallon',
main = 'Distribution of Miles Per Gallon',
col = rainbow(5))
```